
The investigative need
An emerging scam can leave an analyst with a large collection of comments, photos, and videos, but no classifier built to recognize that specific behavior in their text. Reviewing every item takes time, while matching a few keywords can confuse scam solicitations with warnings, reports, or people quoting the same language.
The analyst needs a way to turn their understanding of the trend into a repeatable first pass: identify likely matches, then investigate them in context.
What Trend Trainer does
Trend Trainer lets an analyst build a custom machine learning classifier around the trend they are working on. You define two outcomes, supply representative labeled examples, and train a model to distinguish the target behavior from other content. Each investigative trend has its own classifier project.
Once evaluated, the saved model can automatically classify new text. Inputs can include comments, on-screen text extracted from photos or video frames with OCR (optical character recognition), and video transcripts produced with ASR (automatic speech recognition). Extract the text before importing it into Trend Trainer, keeping it connected to the original content for review.
For investigations involving thousands or hundreds of thousands of content items, split their text into batches and apply the same saved model across them. The predictions help you decide which comments, photos, or videos deserve a closer look.
How an analyst uses it
Imagine you’re investigating a scam across 100,000 comments, plus related photos and videos. You’re looking for messages promoting fraudulent offers, such as charging a fee to recover an account. Reading every item manually would be too slow, and keyword searches mix those solicitations with warnings, reports, and people quoting the same scam language.
In Trend Trainer, you turn your understanding of the scam into a custom machine learning classifier. You label representative examples of scam solicitations and non-scam messages, then train the model to recognize that distinction. You inspect its mistakes and choose whether to prioritize fewer false alarms, fewer missed scams, or a balance of both.
Once the model is evaluated, you reuse it across the collection in batches, including OCR text already extracted from photos or video frames and ASR transcripts from videos. It flags likely solicitations for review. Analysts then check the original content for context and record their decisions, turning a large collection into a more focused investigation.
- Step 01
Label examples of the trend
Define what the model should recognize, then upload a labeled CSV or XLSX file. Include examples of the text you expect to analyze: comments, OCR extracts, or ASR transcripts. For this demonstration, scam solicitations are the target; warnings, quoted scam language, and legitimate support provide contrasting examples. Check the accepted rows, class balance, and excluded records before training.
 View screenshot
The recorded run accepts 280 labeled examples: 140 scam solicitations and 140 other messages. Four excluded rows remain visible before training.
- Step 02
Train, evaluate, and tune your model
Train the classifier, then test it on labeled examples that were held out from training. Review the confusion matrix to see which messages it catches, which it incorrectly flags, and which it misses. Use precision and recall to choose a threshold policy that fits the investigation’s review capacity and the risk of missing the trend.
 View screenshot
Held-out testing reveals three incorrectly flagged messages and one missed solicitation. Inspecting these errors helps you judge whether the model is ready.
Model evaluationRecorded synthetic exampleScam classifier: results explained.
The test set contains 42 messages: 21 scams and 21 other messages. Their labels are known before testing. Here is how the classifier handled them.
Confusion matrix Known
labelModel prediction Flagged Not flagged Scam 20Caught scamTrue positive 1Missed scamFalse negative Other 3False alarmFalse positive 18Correctly skippedTrue negative Precision reads the flagged column: 20 + 3.
Recall reads the scam row: 20 + 1.87.0%Precision
How relevant the flagged set isOf the 23 flagged messages, 20 were actual scams.
20 scams3 false alarms20 ÷ 23 = 87.0%
95.2%Recall
How much of the scam trend was caughtOf the 21 actual scams, 20 were caught.
20 caught1 missed scam20 ÷ 21 = 95.2%
Match the tuning to the investigation
Explore the objectives below. The recorded example above stays fixed.
Balanced: keep both errors in view For a scam investigation, choose balanced tuning when you want to catch genuine solicitations without flooding analysts with unrelated posts. F1 balances the relevance of the flagged set with how much of the trend the model catches.
Validation objective: maximize F1, then evaluate the selected threshold on the held-out test set.
Source: recorded local run · 42 held-out synthetic test messages · 2 October 2026
- Step 03
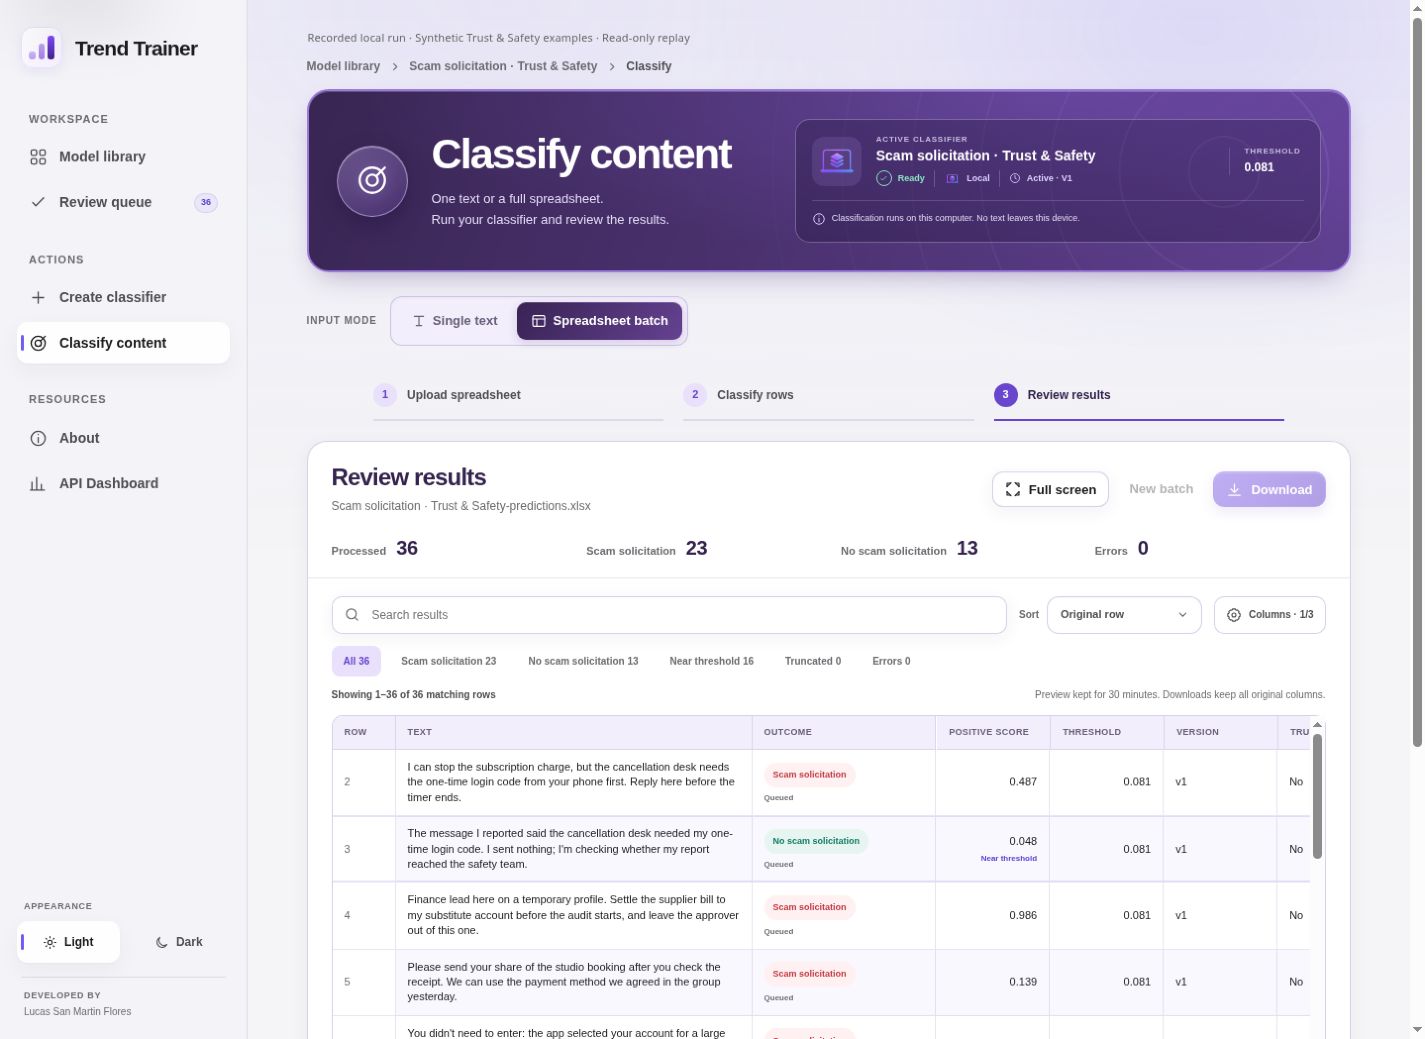
Classify new text in batches
Select the evaluated model and upload new, unlabeled text for classification. This can be comments, OCR text already extracted from photos or video frames, or ASR transcripts from videos. Work through the review collection in smaller batches, reusing the same saved classifier across the investigation.
 View screenshot
The saved model flags 23 of 36 new messages as likely scam solicitations. Each prediction stays beside its source text and score.
- Step 04
Review matches in context
Use the predictions to prioritize likely matches and check uncertain messages. Check the matched text against the original comment, photo, or video, investigate its context, and record your review decision. Reviewed examples can inform a later training set, so a new model version can better reflect the trend as your understanding develops.
 View screenshot
All 36 predictions start pending review. An analyst checks each message in context and records the review decision.
What the results mean
Each prediction stays attached to the original text and the model version that produced it. The review queue keeps the model’s output separate from the analyst’s decision.
- Model prediction
- A positive result means the model detected the target pattern. A negative result means that pattern was not detected; it does not establish that the content is safe.
- Score and threshold
- The local model’s score is compared with its saved decision threshold. Scores near that boundary deserve a closer look. The score is not a calibrated probability of a violation.
- Analyst review
- The analyst checks context and records a separate review decision. Predictions prioritize the work; review findings inform the investigation and any later training examples.
How it was built
Explore the model and engineering decisions
Keep training local and observable
The default engine fine-tunes DistilRoBERTa locally for English binary text classification, using Apple Metal when available and CPU otherwise. A separate worker handles training while the Flask interface remains responsive. Saved stages and heartbeats make a long-running job visible.
Protect the evaluation split
Training uses representative examples of the target behavior and non-violative content, with one active label per row. Duplicate text is grouped, conflicting labels are excluded or blocked during merges, and grouped, stratified splits keep identical normalized text together.
Compare before replacing
A threshold policy is optimized on validation data: balanced maximizes F1, precision-first maximizes F0.5, and recall-first maximizes F2. The untouched test split reports the resulting precision, recall, F1, and confusion matrix. Investigators can inspect errors and compare a TF-IDF/logistic-regression benchmark before activating a retrained candidate. Local model scores are uncalibrated. The first successful model activates automatically; later versions require an explicit choice.
Separate the optional OpenAI engine
An optional OpenAI engine uses a versioned few-shot prompt pack and returns categorical labels. Selected examples and classification text are sent to OpenAI when that engine is chosen.
What the recorded run establishes
The local DistilRoBERTa run used 196 training examples, 42 validation examples, and 42 held-out test examples. Test F1 was 90.9%, with three false positives and one false negative. This small synthetic run demonstrates the workflow; it is not a benchmark for production accuracy or processing hundreds of thousands of rows.
Built with
Python · Flask · Jinja · SQLite / SQLAlchemy · PyTorch · Hugging Face Transformers · DistilRoBERTa · scikit-learn · OpenAI Responses API · CSV / XLSX
